
Crawler Record
| 开发者 | dizzysoft |
|---|---|
| 更新时间 | 2026年9月9日 23:34 |
| PHP版本: | 7.4 及以上 |
| WordPress版本: | 7.1 |
| 版权: | GPLv2 or later |
| 版权网址: | 版权信息 |
详情介绍:
- Bing
- ChatGPT (OpenAI)
- Claude (Anthropic)
- Perplexity
- Meta
- Apple
- Amazon
- DuckDuckGo
- Common Crawl
manage_options can view this information:
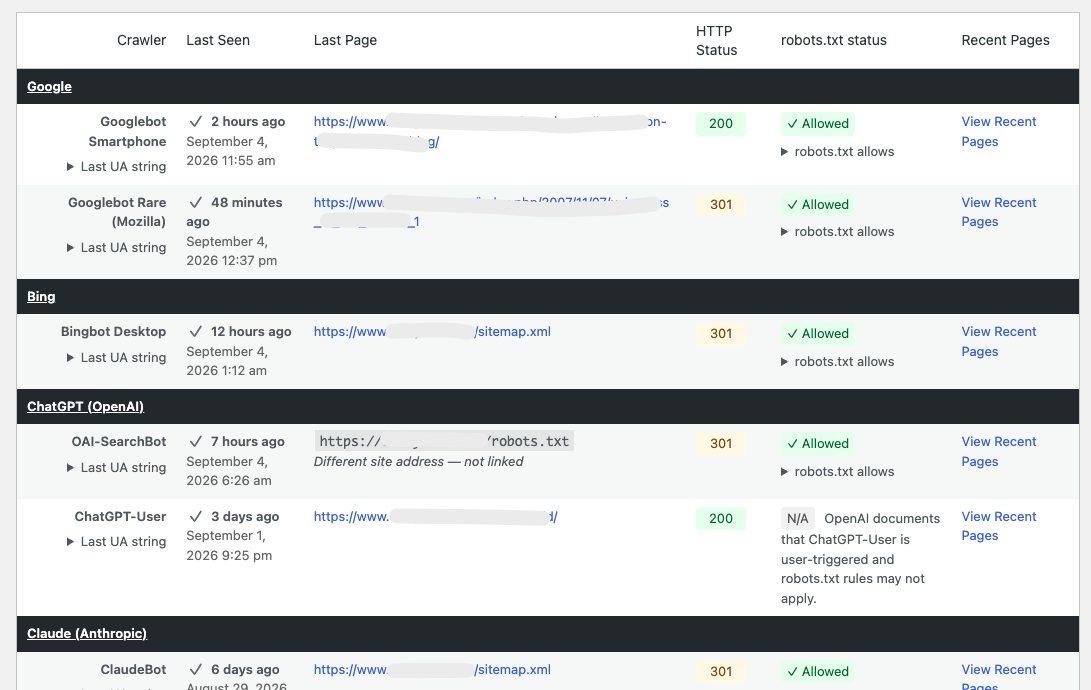
- Admin page: a grouped list of all crawlers, with last seen time, last page, and robots.txt status for the crawler.
- Recent Pages: From the admin page, you can select a crawler and see its latest visited pages, the response status WordPress observed, and a destination when WordPress exposes one for a retained 3xx response.
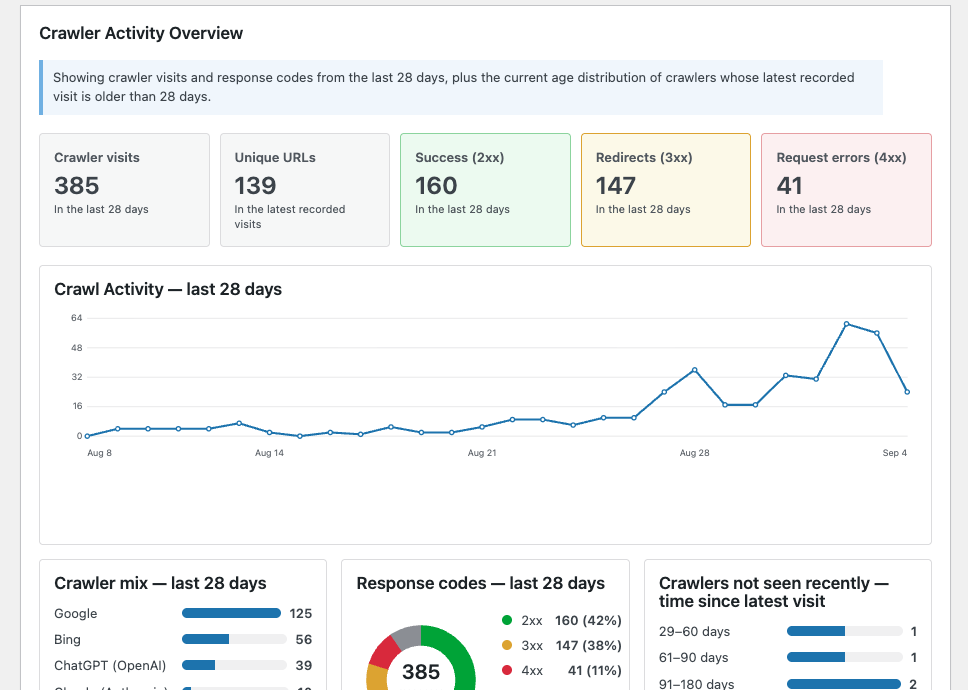
- Crawler Activity Overview: Review 28-day visit totals, response-code health, crawler mix, a daily activity timeline, and crawler staleness. URL reports use up to the 50 most recent recorded visits per crawler.
- Crawler Status Overview: Filter the main dashboard and crawler table by crawlers that visited within 28 days, have become stale, or have never visited. The unfiltered dashboard includes the stale-crawler age distribution alongside current activity; the Stale view focuses on that distribution, latest-visit details, and Recent Pages links instead of empty or potentially misleading historical metrics.
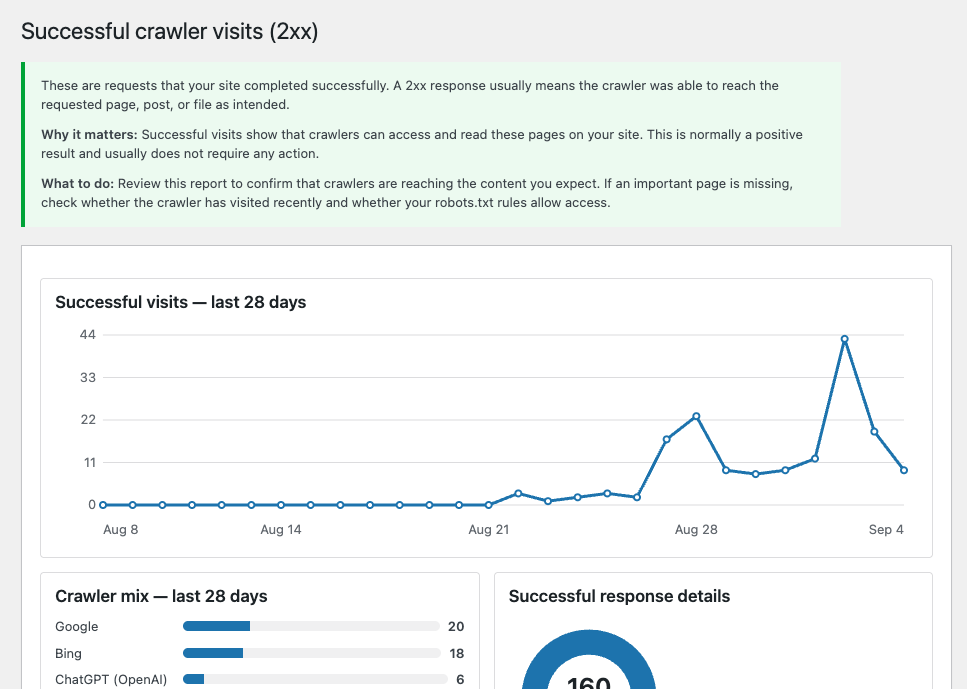
- Header Codes for User-Agents: Did a user-agent successfully visit a page (2xx), receive a 3xx response, or land on a page that was missing or inaccessible (4xx)? Crawler Record will show you. The 3xx report includes every retained 3xx status, including 304 Not Modified; only responses with an observable redirect destination show where the request was sent.
- Admin Bar (front-end): quick-glance status for all user-agent visits.
- Per Page/Post: From the edit screen on any page or post, you can see the last time each crawler visited that page. Administrators can also open the main dashboard or an individual crawler's Recent Pages report from this box.
- Supports common user-agent variants for Google, Bing, OpenAI (ChatGPT), Anthropic (Claude), Perplexity, Meta, Apple, Amazon, DuckDuckGo, and Common Crawl.
- robots.txt status computed from a local physical or WordPress virtual source without outbound requests.
- Can only track crawlers from the time the plugin is installed—it cannot reconstruct earlier visits.
- Per-post “last seen” timestamp and user-agent metadata update at most once every 10 minutes by default. Separately, rapid same-crawler, same-URL, same-status visits are suppressed for 30 seconds, and a high emergency ceiling retains up to 50 visits per crawler per minute.
- Concurrent requests matching the same crawler are not coordinated. One database write may replace another, causing a visit to be absent from recent history or daily totals, or causing the latest-visit fields to reflect whichever write finished last. Dashboard totals are therefore approximate retained activity rather than an exact raw access log because of throttling, retention limits, and possible concurrent writes.
- Response codes are available only for requests that reach WordPress. Responses served earlier by a CDN, web server, static cache, or security layer are outside the plugin's visibility.
- The 3xx report includes all retained 3xx statuses, including 304 Not Modified. Redirect destinations are available only when WordPress/PHP exposes a Location header. Redirects issued before WordPress runs cannot be recorded, and a followed destination is retained as a separate visit if it reaches WordPress.
- Stored source and redirect URLs include scheme, validated host, optional port, and path. Query strings are omitted to avoid retaining sensitive tokens, personal data, and high-cardinality tracking parameters. Reverse-proxy configuration can affect the scheme WordPress observes.
- URLs up to 114 characters are stored normally. URLs from 115 through 1,028 characters retain the visit with a 100-character prefix and an excessive-length marker; they are displayed with an ellipsis and are not linked. URLs longer than 1,028 characters are omitted from URL-level reports. Sitewide tracking for such requests is subject to the 30-second suppression window, while applicable per-post metadata uses its separate 10-minute throttle.
安装:
- Upload the plugin folder to
/wp-content/plugins/, or install via the admin Plugins screen. - Activate the plugin.
- Visit Crawler Record under Admin → Crawler Record to review crawler activity.
屏幕截图:
常见问题:
Why are there no crawler visits recorded?
This plugin can only begin tracking crawler/bot visits from the time you install it—not before. It may take several days or weeks, depending on your website's popularity, before a crawler visits.
Why do I see the indexing warning?
If Settings → Reading → Discourage search engines is enabled, the plugin explains that WordPress asks compliant search engines not to index the site. This does not prevent access, so robots.txt status is evaluated separately.
Why doesn't this data align with my website visitors?
You're comparing two different things: user-agents and human visitors. This plugin measures requests from crawler user-agents, not visits from people.
How can I get a user-agent to visit my website?
Several factors contribute, including your website's authority, popularity, internal linking, and links from other trusted websites. A crawler visit does not guarantee that a platform will add the page to its index.
更新日志:
- Added a 28-day activity overview showing crawler trends, crawler mix, response-code health, and crawlers that are recently active, stale, or not yet seen.
- Added focused reports for successful requests, redirects, and missing or inaccessible pages, with frequently requested URLs and recent visit details.
- Added individual crawler dashboards with recent pages, response statuses, redirect destinations, plain-language descriptions, and links to official documentation.
- Added Amazonbot, Amzn-SearchBot, Amzn-User, and improved recognition of crawler variants from other platforms.
- Improved robots.txt reporting with clearer crawler-specific results and a separate explanation of WordPress’s search-engine visibility setting.
- Improved dashboard clarity, accessibility, keyboard navigation, chart readability, mobile layouts, the post editor summary, and the front-end admin bar.
- Confirmed compatibility with WordPress 7.1.
- Confirmed compatibility with WP 7.0+
- Improved crawler detection accuracy and reduced false matches- especially with Bing.
- Made version matching more resilient to future changes.
- Added support for the Common Crawl (CCBot): https://commoncrawl.org/ccbot
- Improved handling of user-triggered agents and
robots.txtbehavior. - Improved labels and administrative reporting.
- Added crawler-specific fallback behavior where required.
- Removed irrelevant history links for non-crawling control tokens.
- Removed reference to Microsoft Copilot, since it uses Bingbot.
- Minor changes and updates.
- Added Recent Pages history for each crawler.
- Added support for additional crawler variants including Google-Agent (mobile and desktop), Google-Extended, Bing (Search, Chat, and Copilot), Claude-SearchBot, Perplexity-User, DuckDuckGo AI, Applebot-Extended, and Meta-ExternalFetcher.
- Improved crawler tracking for non-post frontend URLs such as archives, taxonomy pages, and other site URLs.
- Improved site-wide reporting so the latest page visited by each crawler is more accurate.
- Improved admin bar reporting for both singular content and non-singular frontend URLs.
- Improved robots.txt reporting with clearer diagnostics showing the matched group and rule.
- Added informational robots status handling for agents that may ignore or bypass robots.txt, such as Google-Agent and Meta-ExternalFetcher.
- Improved handling of the WordPress “Discourage search engines” setting with clearer blocked-status warnings in the admin interface.
- Improved storage of recent crawler activity with bounded recent-page history per agent.
- Fixed error on any WP archive pages (pages that list posts).
- Updated for WordPress 6.9
- Now monitoring for Meta and Apple User-Agents
- More accurate site-wide UA reporting.
- Ensured video tutorial appears on all admin screens.
- Fixed small code errors.
- Google updated its user-agents, so I updated the matching strings to account for these changes.
- The robots.txt checker wasn't actually working. It does now.
- When you look at the report in the admin section, the robots checker is looking for a site-wide rule; when you look at the back-end of a page, the robots checker is looking at that particular page.
- If a page is blocked by the robots.txt file, a link appears sending you to the robots.txt file.
- Added a video to explain how to use this plugin.
- Clarified distinction between Google bots.
- Better distinguishes Bingbots.
- Cosmetic changes to page in admin section.
- Clearer documentation.
- First public release